Sunday, September 27, 2026

The shell script passed. The cluster test could not deploy the intercept.

The shell script passed because a person was holding the CLI. The automated test had no CLI to hold. That is the bug in tekton-dag that was found while moving pull-request intercepts off the laptop and into the cluster.

It turned up inside a larger experiment. I am running eight or more projects at once, and Obsidian is the shared record between the Cursor sessions doing that work. Most of the time the record is there so a session can take the next bounded item, finish it, and leave the queue understandable. This one was the other use. A problem popped up on one project, and the same notes had to carry a deep fix without losing the rest.

A pull request builds the changed app and deploys it as a PR pod next to the live stack. Traffic that carries x-dev-session: pr-N must be served by that pod. Traffic that does not carry the header must stay on the baseline, untouched. The pipeline is supposed to install that split itself and then prove it. For a long time the install step was a Telepresence intercept, and the proof was a script that exited zero.

Two ways of running the same test

From a laptop, the path is a handful of commands. Install the traffic manager, run telepresence intercept, name the deployment, set the header, and point the intercepted traffic at a local process. The person running the script has an admin kubeconfig. The CLI is on their PATH. Those runs intercepted. That is what the session notes remembered as "E2E with Telepresence intercepts passing."

The refactor put the same job inside Tekton. A task pod in the cluster was supposed to deploy the intercept with nobody at a keyboard. The sidecar we gave it was ghcr.io/telepresenceio/tel2:2.20.0. That image is the traffic agent. It contains one binary, traffic. telepresence is not in it. telepresence helm install failed with not found, the container exited, and kubectl wait still succeeded because the pod was briefly Ready during a ten-second sleep.

You cannot deploy this intercept without the CLI commands. Connect, create the intercept, set the header filter, and aim it at the PR workload are all telepresence subcommands. The in-cluster image cannot run them. The automated test was not a stricter version of the shell script. It was a different program, missing the only tool that does the work.

The check on top of that was warn-only. It printed NOT CONFIRMED and exited 0. Automated runs on main stayed green through the middle of September. On 26 September the check was changed to fail when a hop was not confirmed. The next run on main went red. Telepresence had not changed. The test had stopped agreeing with a log line.

Why copying the CLI into the pod was not the fix

We did try to put a real Telepresence CLI in the cluster. A client pod with the CLI, its own service account, a tun device, and a privileged namespace still could not hold the intercept the way a laptop does.

  • A newer CLI could not create intercepts against the traffic manager already in the cluster. The client and the manager have to match closely.
  • Once a matching CLI did create an intercept, header-matched requests hung. The client image had no iptables, so the session that carries stolen traffic back to the handler never started.
  • A whole-port intercept, which does not need the header filter, stole baseline traffic too. That breaks the contract.
  • Injecting the traffic agent restarts the live deployment. The laptop workflow does not do that to the running stack in the same way, because the intercepted process is on the laptop.

The net finding is to take Telepresence out of the in-cluster tests. It remains a fine laptop tool: install it on a workstation, run the CLI, debug against the cluster. It does not belong in a pipeline that has to deploy the intercept from a pod. Pull request 109 removes the in-cluster task, the traffic-manager install from the runner, and the Telepresence leg of the test matrix.

What the two paths actually were

Shell script, from a laptop. This one intercepted.
Laptop
telepresence CLI
admin kubeconfig
header filter set by a command
→ Traffic manager
in the cluster
takes the CLI's intercept
→ Split
header → local process
no header → baseline
Automated job, inside the cluster. This one could not deploy.
Tekton task pod
image tel2:2.20.0
binary: traffic
no telepresence CLI
→ No command to run
cannot connect
cannot create the intercept
cannot set the header
→ Nothing served
PR pod was a sleep loop
check printed NOT CONFIRMED
exit code 0

Why the manual run did not become the CI run

The manual test and the CI job shared a name. They did not share a procedure. A person at a laptop was doing five things the pipeline never did, and each one was load-bearing. Drop any of them and the intercept is a different test.

What the person supplied What the CI job had instead
The telepresence CLI on a laptop PATH, and the commands that create the intercept. A pod image whose only binary is traffic. The commands the script ran were not in the container.
An admin kubeconfig. The CLI could install, connect, and edit the live workload. A namespace service account. The same binary, run as that account, is forbidden from the calls the laptop made.
A real process on the laptop, which answered the stolen request. A PR pod whose command was while true; do echo "PR build"; sleep 30; done. It could not answer HTTP.
Eyes on the full terminal. A failed connect was the next line of output. An artifact collector that ran kubectl logs without asking for the whole log. The default is ten lines per container, so the error a person would have read was cut off.
A pass the person could see: the request landed on their process, and a request without the header did not. A pass the script could exit: print NOT CONFIRMED, then exit 0. Green meant the task ended, not that the pod served the request.

That is why months of green CI did not contradict a passing shell script, and did not confirm one either. The script was evidence about a laptop session. CI was evidence that a different program returned zero. Wiring the script into GitHub Actions would not have closed the gap, because the script's success still depended on the person: their binary, their credentials, and their reading of the log.

The same split showed up again after the pipeline moved to mirrord, which can run its CLI in a pod. A hand test in the cluster routed correctly. The pipeline run of that same idea did not. Two details that a person fills in without noticing:

  • The account. The hand test used an admin user. The proxy pod used the namespace default service account, which is not allowed to create the agent or to open the port-forward the agent connection needs. The deploy step only waited for Ready. A container with no readiness probe is Ready the instant it starts, including one that exits a second later on Forbidden. The hand test never hit that account, so it never hit that failure.
  • The header string. mirrord matches the header as name: value, colon then a space. The hand test used that form. The task passed x-dev-session:pr-N with no space. The filter could not match, every request stayed on the baseline, and a check that only looked for the header echoed back in the response still printed pass. Both pods echo the header. Echo is not identity.
A manual pass proves the tool in the hands of the person who ran it. It does not prove the job. CI has to run the same command, as the same kind of account, against a process that can answer, and fail when the PR pod's own log does not show the matched request and only the matched request.

How MetalBear fixed the in-cluster path

MetalBear ships mirrord as a CLI whose job is to run a process in the context of the cluster. The CLI does not have to live on a laptop. The tool image for the pipeline contains it. The task starts a proxy pod, and that pod runs mirrord exec.

mirrord creates an agent pod beside the live deployment. The agent is what steals traffic. Steal mode with an HTTP header filter takes only the requests whose header matches x-dev-session: pr-N and hands them to the process mirrord is wrapping. In the pipeline that process is a small relay to the PR pod, which is running the built image as the real app. Requests that do not match stay on the baseline pods. The live deployment is not restarted to install a sidecar, and the client pod does not need a tun device or iptables.

In-cluster intercept with mirrord. The CLI runs in the pod. The agent does the split.
1. Tekton task starts a proxy pod as its own service account, not as the namespace default. The pod's image includes the mirrord CLI.
2. mirrord exec in that pod creates the agent next to the target deployment and connects to it through the Kubernetes API. The filter is (?i)^x-dev-session: pr-N$. mirrord matches the header as name: value, colon then space. A filter written without the space never matches.
3. Agent, steal + header filter. Matching request → relay → PR pod (the built app). Any other request → baseline pods, unchanged.
4. Proof, from the PR pod's access log. A marked URL with the header must show up there. The same mark without the header must not. Remove the intercept and the first check goes red. Steal every request and the second check goes red.
                incoming request
                       │
                       ▼
              mirrord agent (in cluster)
              header filter on the Service
                    │            │
         x-dev-session          no match
           : pr-N                  │
              │                    ▼
              ▼              baseline pods
         proxy pod            (live stack)
         mirrord CLI
              │
              ▼  relay
           PR pod
     (built image, real app)
              │
              ▼
     access log must contain
     the matched probe only

The first honest pass of that proof is what the shell scripts never had to show. A response that echoes pr-N is not evidence: the baseline echoes the same header. Pod Ready is not evidence either: a container with no readiness probe is Ready the instant it starts, including a process that crashed a second later. The access log is the pod admitting it saw the request. The unmatched probe is the control that says it did not see the other one.

mirrord is in the test matrix because the pipeline can deploy it. The CLI is in the image, the agent is a pod the task is allowed to create, and the filter lives in config the task writes. Telepresence's in-cluster image could not issue the commands the shell script depended on.

Lessons

None of these showed up as a failing assertion the first time. Each one showed up as a story that was already believed.

  • A manual pass is about the person who ran it. Their binary, their credentials, the string they typed, and the log they read. The job has to be given those same ingredients or it is a different test.
  • A green pipeline is only as honest as its weakest check. Exit 0 on NOT CONFIRMED is not a result. Pod Ready is not a result. A response that echoes the header is not a result, because the baseline echoes it too. The check needs a negative control that fails when the feature is absent.
  • Keep the log you will debug from. kubectl logs on a selector keeps ten lines per container unless you ask for the rest. The line that explained the failure was in the part that was thrown away.
  • Do not match the word ERROR and call it a failure. A healthy tool prints ERROR for noise. The gate has to name the fatal message. A gate that matches the noise stops the run that was about to show you the real bug.
  • Find the bug on a cluster you can still see. Four failures in a row were each debugged from a log zip after CI had deleted the cluster. Every one of them was a two-minute question with kubectl on a live local cluster. CI is the clean confirmation after that, not the place the diagnosis happens.
  • Write down the path you closed, and why. "E2E passed" was already in the notes from the spring. Without a newer note that says that sentence was wrong, the next session will treat it as the fact and spend another afternoon on it.

The notes were how the next session knew where to start

The experiment has two speeds, and I wanted to know whether one record could serve both.

The fast speed is a batch. Across the other projects the work is a list of bounded items: one check, one hole, one small change, then stop. A session should be able to open a project, read what is left, do that item, and write down where it stopped. Nobody re-briefs it. The vault is the queue. That is the automation. Not a scheduler inside the notes, and not the notes launching the next session. Cursor does the work. Obsidian is what lets the next session start from the item instead of from a blank chat, so eight projects can move without eight briefings.

The slow speed is a problem that will not fit in an item. This intercept was that. It did not fit in one chat. Through the day the story changed: both backends were green, then I rejected a whole-port intercept, then both greens were false, then the in-cluster Telepresence path was closed, then mirrord's own green was a race. A later Cursor session does not remember that. It remembers the last thing someone typed, or an older note that says the test passed. If the notes only knew how to hand out the next batch item, this fix would have been a fresh investigation every time I came back to it, and the other projects would have stalled while I held the context in my head.

The record that survived is in Obsidian, written and read through obsidian-mcp. Three notes, and they do different jobs:

  • Project state says what done means right now. Merge only when a request with the session header shows up in the PR pod's log, and a request without it does not. A green that cannot show that is not done.
  • A working note is the timeline of what we believed against what the artifacts showed. February's "E2E passing" sits in the same table as the sleep loop and the exit code. When the next session starts, it reads the correction before it reads the claim.
  • A decision freezes the choice and the alternatives that were rejected. mirrord is the in-cluster backend. Telepresence stays on the laptop. Do not bring the in-cluster path back without the same routing proof. Debug on the local cluster; let CI confirm.

Cursor calls that vault before the work, not after a wrong turn. get_project_context returns the state, the latest session, and the decisions. search_memory finds the decision by the question you actually have, instead of by which chat happens to be open. When a choice should outlive the session, record_decision writes it as its own note. When the session stops, capture_work_session appends what changed and what the next person should not redo.

That is what kept the solution moving. The next session did not "fix" the red build by letting NOT CONFIRMED exit 0 again, because the state file said the earlier green was empty. It did not spend another round of CI on an in-cluster Telepresence sidecar, because the decision already recorded why that path was closed. It took the next red run to the local cluster, because the decision said a log zip is the wrong tool for a question kubectl can answer while the pod still exists.

The notes were also wrong on the same night, and that is part of the lesson. An early write said mirrord had met the contract. An audit a little later showed its green was the same kind of lie: the proxy died on a forbidden call, Ready flickered, and the response echoed a header the baseline would have echoed anyway. The working note was corrected in place. A vault that cannot be corrected just launders the last confident sentence, which is how "E2E passing" survived from the spring until the check was made fail-closed.

The same notes do both jobs. They hand the next bounded item to a session that is working through a batch, and they hold a deep fix when a problem pops up, including the paths already closed. The notes did not find this bug. The artifacts did. What the experiment showed is that I did not have to drop the other projects to stay inside this one.

Obsidian is the scratch pad. The repo ledger is the lesson.

Something about the relationship to SDLC-SPDD is coming into focus, and I do not want to pretend it was designed this way on day one.

SDLC-SPDD still guides. It says which phase the work is in, what done means, and what is allowed to become a permanent record. It does not have to hold the intermediate work. That gets pushed to Obsidian: the scratch pad a session writes while the work is still messy. Project state, the timeline of what we believed, the decision, the correction an hour later, the CI run that is still red, the guess that turned out to be wrong. That accumulation is the point. A deep fix needs the noise, because the noise is where the last wrong sentence is written down and then crossed out. A batch needs it too, because "where this item stopped" is not a lesson yet. It is a handoff.

That pile should not become the memory of the repository. A later change in tekton-dag does not need the night's chronology, the ten-line log truncation, or the hour where both backends looked green. It needs the sentence that survived the night. A manual pass does not prove the job. A green check needs a negative control. Do not throw away the log you will debug from. Do not fail a healthy tool for printing ERROR. Find the bug on a cluster you can still see, and let CI confirm. Write down the path you closed.

Those sentences are what come back. The guide stays in charge of the return trip. A capture during the work is staged and stays out of git. At the end of the work, an accept step promotes what is worth keeping into the committed lessons ledger. Nothing else is supposed to land there, and the ledger is not edited by hand to make a story fit. The scratch pad can be wrong at 9pm and corrected at 11. The ledger should only receive the correction that still matters after the noise has been thrown away. Intermediate work lives in Obsidian. SDLC-SPDD keeps guiding, and it keeps the lesson.

SDLC-SPDD guides. Intermediate work goes to Obsidian. Only a distilled lesson comes back.
1. SDLC-SPDD guides
Which phase this is. What done means. What is allowed to become a permanent record. The intermediate notes do not go here.
↓ intermediate work pushed out, noise included
2. Obsidian — the scratch pad
Project state, the believed-versus-true timeline, the decision, the handoff ("stopped here"). This pile stays here. It is not the memory of the repository.
Stays in the vault
chronology
false starts
CI run still red
a sentence corrected at 11pm
→ 3. Distill
one lesson that is still true after the noise is thrown away
a manual pass does not prove the job
↓ staged, not committed yet
4. Accept
Review the staged lesson. Promote it, or leave it. The scratch pad is not copied across.
↓ committed
5. SDLC-SPDD lessons ledger
The sentence the next change can retrieve. Not the night. Not edited by hand to make a story fit.
The guide stays. The scratch pad holds the middle. The ledger receives the lesson. Intermediate work is pushed to Obsidian so the repository does not fill up with the night. What comes back is small enough that the next change can retrieve it without replaying that night.

What I will trust a green run to mean

A green intercept job has to print that the PR pod served the matched request and did not serve the unmatched one. Local kind produced that line. The intercept job on pull request 109 then produced it on a clean cluster, and that pull request is merged. A laptop script from last spring is not what made it done.

If you are wiring the same kind of test: run the command your script runs from inside the job that is supposed to replace the script. If that command is not in the image, you are not automating the test. You are automating the exit code.

The change is tekton-dag pull request 109. mirrord's own model is documented at mirrord.dev.

Five additions that improve maintainability and code quality

The goal was to improve maintainability and code quality across the repositories I ship. The two are not the same thing, and both matter. Maintainability is the cost of the next change: how long it takes an engineer to open the code, make a change, and move on. Code quality is whether that change did what they meant and nothing else moved. Low quality makes every change a risk. Low maintainability makes every change slow. In September 2026 I made five additions to every repository to improve both. This post is about what was added and what each addition does for each.

Why a score for the whole repository fails

The common approach is one number for the whole code base. Every file is graded, and the build goes red when the total is over a line. It sounds like discipline. In practice the number is driven by old files nobody is changing. To move it, an engineer opens a file the product does not need touched, rewrites it, and writes tests for the rewrite. The suite grows. The number moves. Maintainability did not improve, because the next real change was never in that file. Quality did not improve either, because a rewrite of working code is a new place for a defect. The team is working for the number.

The additions below take a different route to both. Each one grades the change in front of it. Code the change did not touch is left alone. Problems that already exist stay written down, and nobody is allowed to delete the list to make the build pass.

The five additions

Each addition is one check in the build, and each check is one question. A manager can ask it of any change and get a yes or a no.

1. Did this change add a new problem on the lines it touched?
Only the lines this change wrote are graded. A small edit in an old, tangled file passes if the edit itself is clean. A new problem on a changed line fails.
Maintainability: the code stops getting worse where people are working. Every change that lands is at least as clean as what it replaced, so the next change in that file is no harder than this one.
Quality: the problems this check catches are the ones that hide defects: a branch nobody can follow, a function doing four jobs, a value used before it is checked. Refusing them on the changed line keeps them out of the product.

2. Is this file both tangled and the one people keep editing?
A file is called out only when both are true. Hard to change, and changed often. Difficulty alone is not a project. A tangled file nobody opens costs nothing until somebody opens it.
Maintainability: cleanup goes to the file that is slowing down every edit. That is where a planned cleanup buys back the most time, and the rest of the debt is left where it is.
Quality: a file that is both tangled and edited often is where defects come from. Every edit to it is a chance to break something nobody can see. Cleaning that file, and only that file, removes the most defect risk for the least work.

3. Did this change break one rule the repository is not allowed to break?
Each repository names one rule that matters more than any style score, and tests it in the build. A post stays a draft unless publishing is turned on. A log must not contain a password. A fork must not grow a path back to the project it came from.
Maintainability: the rule holds without anyone having to remember it. A new engineer, or a busy one, cannot break it by accident, and nobody has to re-learn it by cleaning up after a mistake.
Quality: these are the defects that matter most and are found latest. A post that went live, a password in a log, a change sent to the wrong project. The check turns each one from an incident into a red build.

4. Did someone edit the written list of old problems so the build would pass?
Existing problems are recorded. A new one fails the build. The list may shrink when a problem is actually fixed. It may not shrink because the build was red.
Maintainability: the debt stays visible and readable, so decisions about it are made on facts rather than on a number someone adjusted.
Quality: a green build means the change was clean. It does not mean the list was trimmed. Without this check the other four can be switched off quietly, and the quality signal from the build is gone.

5. Do the tests for one chosen piece of the product still catch a mistake they used to catch?
The build breaks that piece on purpose and expects the tests to notice. If they do not, the build fails. Each repository checks one piece, because doing this to everything on every change costs more than it returns. A check that tests nothing fails.
Maintainability: an engineer can change that piece and trust the tests to catch what they broke. A suite nobody trusts makes every change slower, because the engineer has to check by hand what the tests should have checked.
Quality: a large test suite is not a safe one. Tests that pass no matter what the code does give a green build and no protection. This check is the only one of the five that measures whether the tests can find a defect at all.

How the additions compound

None of these is dramatic on its own. Together, over months, they bring the cost of the next change down and the defect rate down with it.

On maintainability: the parts of the product that get the most attention are also the parts the checks run on most often, so they get steadily easier to change. Old debt does not leak into new work, because the first check refuses it at the line. The second turns cleanup from a reaction to a score into a decision about a named file with a known cost.

On quality: the fifth check keeps the suite honest, so a green build carries information. The fourth keeps the record honest, so the trend is real. The third holds the rules that a busy team would otherwise re-learn by breaking them in production. Together they mean that when the build says a change is fine, it is fine, and when it says stop, there is a defect or a risk behind it.

What a manager should expect to see: fewer surprises in review, because the build already refused the change that made things worse; cleanup work that can be explained in one sentence, because a check named the file; and a build that is red for a reason someone can act on today, rather than for a number the team has learned to route around.

What this does not do: it does not pay down the existing debt on a schedule, and it does not promise the number goes to zero. The debt is written down and left alone until a change touches it or a hotspot earns a cleanup. That is on purpose. The alternative is a team working for the number.

What it costs

No new platform, no new licence, no new role. Each check uses the grading tool the language already has, running inside the build the repository already runs. The first four add minutes to a build. The fifth is the expensive one, which is why it is limited to one piece of the product per repository and not the whole thing.

There is a one-time cost when the checks arrive. The record of existing problems has to be written down once, and someone has to read the first hotspot list and decide which file, if any, earns a cleanup. After that, the cost is paid by the engineer whose change turned the build red, on that change, the same day. It does not become a backlog.

The cost that goes away is the one nobody was tracking: the hours spent on cleanup the product did not ask for, the tests written to cover that cleanup, and the review time spent on both.

How to tell it is working

A manager does not need to read the code to see whether this is holding. The signals are in the build and the review queue.

  • The record of old problems only shrinks when a fix lands. If it drops without a corresponding change, someone edited it, and the fourth check should have failed. If it never drops, the hotspot list is not being acted on.
  • Hotspot cleanups can be named. Each one points at a file that was both tangled and edited often. If cleanup work cannot be tied to a named file from the list, it is the old behaviour coming back.
  • Red builds are fixed inside the change that caused them. Not as a follow-on ticket, not as a cleanup epic. If red builds are turning into tickets, the checks are grading the wrong thing.
  • Review comments move from style to behaviour. The build has already said no to the change that made the code worse. Reviewers can spend their attention on whether the change does what it claims.
  • Time from open to merge does not grow as the code base grows. That is the cost of the next change, measured directly. It is the number this whole thing exists to hold flat.

If the record shrinks honestly, cleanup has a name, red builds are fixed in place, and merge time holds, the checks are doing their job. If the team starts routing around a check, that is the signal to look at the check, not the team.

Where the checks run

The same five checks, in the form each language already supports, on every repository below. They sit on each repository's maintainability branch until that branch lands on the default branch.

Friday, September 11, 2026

One day with Obsidian MCP — coordinating my agents and experimenting with papers

Today my Obsidian vault was not just a notebook. It was the shared desk for a collection of Cursor agents working across my projects—and the filing system that finally made my paper work manageable.

I used obsidian-mcp throughout the day. Agents opened project context, selected bounded work, recorded decisions, updated status, and left session handoffs for the next agent. At the same time, research agents used the same vault to turn a loose experiment in documenting my projects as papers into seven organized manuscript tracks with evidence, references, metadata, and publication boundaries.

The result was not one giant chat. It was many focused sessions sharing durable Markdown.

The vault was the common layer

Each project has a small set of files that both I and the agents can read:

Project State.md          objective, current state, active work, next steps
Sessions/2026-09-11.md    what each agent changed and where it stopped
Decisions/2026-09-11-*.md why an engineering choice should survive the chat
TODO/*.md                 work that can be selected and tracked

Before substantial work, an agent calls get_project_context. That returns the current brief plus recent sessions and decisions. It does not require loading the whole vault or finding the right old chat.

After meaningful work, capture_work_session appends a summary with the repository, branch, commit, changed-file summary, decisions, and next steps. When an engineering choice needs to stick, record_decision gives it a separate note. When I need to understand why a boundary exists, search_memory finds the earlier reasoning.

The task tools make the vault operational. Agents can list_open_tasks, claim_task, complete_task, block_task, and unblock_task. A task moves through the workflow without reconstructing the entire Project State file. Ambiguous matches fail instead of moving the wrong item.

What the agents worked on today

The session notes show how broad the day was. Different agents worked on different repositories, but they used the same memory pattern.

  • SDLC-SPDD orchestrator: agents tightened verification receipts, review scope, installer behavior, CI evidence, and quality-gate honesty. The vault preserved why a real validation receipt counts and why a skipped live graph cannot be reported as proof.
  • Uberorchbot: agents added plugin and CI guardrails around the Obsidian work queue, skill catalogs, the archived control plane, and repository allowlists. The durable state kept the product on its Cursor plugin and Automations path instead of reviving an abandoned Spring control plane.
  • obsidian-mcp: the memory system improved from its own usage. Agents hardened task claiming, queue synchronization, cross-source matching, read-path redaction, and CI. Problems discovered while coordinating agents became focused improvements to the coordinator.
  • slm-setup: agents worked through local-model runtime safety, token-cap behavior, CI checks, official model tags, and harder evaluation jobs. Decisions recorded which conditions fail, warn, or require a live operator run.
  • documentation-generator: agents closed gaps in visual-sync validation, timestamps, scene specs, audio and LFS checks, scene compilation, and composition. The notes kept each fail-closed change separate instead of turning the work into one unbounded repair session.
  • memory-os and embabel-v1-learning: agents strengthened evaluation, timeline handling, dependency-pin checks, Pages validation, and publishing safeguards without rebuilding media that was outside the task.
  • chatbot: agents worked on structural citation checks, channel CI, GraphRAG testing, opt-in smoke assertions, and the boundary with the commerce product.
  • open-commerce-platform: agents recorded checkout, reservation, payment reconciliation, runtime topology, ratings-goal, and playbook-rematching decisions so later sessions do not re-argue the same product contracts.
  • cdk-cost-killer: agents kept infrastructure cleanup safe by preserving dry-run defaults, skipped bootstrap resources, stack-name boundaries, and the rule that CI never performs a live apply.
  • Guide-related work: agents preserved fork-local rules, pin and tag discipline, and CI checks without turning the work into an upstream contribution path.
  • Fleet review: the vault recorded the selected inspection tools and their roles instead of leaving that choice buried in an evaluation chat.

This is what using Obsidian MCP across agents looked like in practice: retrieve a narrow brief, do one bounded piece of work, record the durable choice, and leave the repository in a state the next session can understand.

Then there was the paper work

The paper organization was not a side note. It was one of the largest uses of the vault today.

I had a broad set of repositories that might become technical papers. Without a durable structure, every research session could generate another outline, another reference list, or another publication idea without agreeing on what the actual papers were.

The vault turned that into an organized documentation experiment. I am exploring whether a paper-style structure can explain the purpose, design, evidence, and limitations of my work more rigorously than ordinary project notes. I am not claiming that these are finished academic papers or committing to publish them.

The experiment currently has seven applicable tracks: P01–P05, P07, and P08. They cover the SDLC-SPDD orchestrator, Uberorchbot, the local coding SLM, memoryOS, documentation-generator, open-commerce-platform, and chatbot.

Eight other candidates—P06 and P09–P15—were explicitly removed because they were not appropriate paper projects. That decision is as important as creating the seven remaining tracks. It prevents a future agent from seeing an old idea and rebuilding an inapplicable manuscript pack.

Each active paper track now has a repeatable set of artifacts:

  • a repository purpose and architecture baseline taken from committed code;
  • an outline and working manuscript draft;
  • an evidence pack tied to exact repository snapshots;
  • a prior-art review and structured bibliography;
  • results and claim-support records;
  • normalized metadata;
  • a deposit sheet that remains preparation, not permission to publish.

Shared research tasks handled the administrative questions once for all seven tracks: the intersection of Zenodo and TechRxiv rules, manuscript scope, PDF format, metadata fields, DOI ordering, AI disclosure, authorship, and the boundary between a software record and a preprint.

One normalized manuscript guide now says that the abstract must agree everywhere—the draft, metadata, and deposit sheet. A shared YAML schema maps fields to both venues. References use stable IDs before print numbers are assigned. Research notes distinguish official sources from open questions.

This is documentation research, not a publication commitment. The agents organize evidence and draft paper-style artifacts. Creator identity, ORCID, technical claim approval, final prose review, PDF approval, DOI creation, and any deposit remain human-controlled. Today’s work was an experiment in documenting the projects; it was not an automated submission run.

That distinction would be easy to lose in chat. In the vault it is part of the project state and decision history. Every agent sees the same boundary.

How this helped me use my plan

Organizing the work also helped me use the model capacity already included in my Cursor plan. Instead of leaving quota unused because I could not keep enough work straight, I had a queue of legitimate, scoped tasks that different agents could execute.

Standard and Auto capacity could take bounded documentation, testing, and guardrail work. Premium capacity could take harder implementation, architecture, review, and research synthesis. The vault made it possible to keep those sessions moving and use the plan productively without relying on one chat to remember the entire lab.

Obsidian also kept the token burn from becoming busywork. If a task was inapplicable, I removed it. If a decision required a human, the agent stopped at the boundary. If the queue was empty, the correct action was to stop—not invent another project merely to consume quota.

What changed for me

Before this workflow, chats were where work happened and where context disappeared. Today, chats were workers. The vault was the durable system.

I could move between software hardening, agent tooling, local models, commerce, documentation video, infrastructure safety, and research because every project had a current brief and every meaningful session left a handoff. I could also open Obsidian and see the paper experiment as a set of linked documentation artifacts instead of a pile of manuscript ideas.

That is the practical value of Obsidian MCP for me: it helped many agents work as part of one day, helped me use the AI capacity I was already paying for, and organized both engineering work and literal paper work in files I can still read after every chat is gone.

Source: github.com/jmjava/obsidian-mcp
Related: Uberorchbot · SDLC-SPDD orchestrator · local coding SLM setup

Sunday, September 06, 2026

Same MCP, next host — Halo on the slm-setup roadmap

The GPU can move. The bridge should not. The first slm-setup post described a split: a premium cloud model plans and reviews, while a small language model (SLM) on private hardware handles bounded generation through MCP tools. The private model runs under Ollama, an open-source server for running language models locally. “Halo” here means a PC built around AMD’s Strix Halo design, which can share up to 128GB of unified memory between the CPU and integrated graphics. The question is whether that memory makes Halo a worthwhile later Ollama host — not whether to build a second coding system.

Two C4 diagrams make the roadmap concrete. The context view shows who talks to what; the deployment view shows which machine runs each part. The software boundary stays fixed while the machine hosting Ollama changes.

What stays fixed

C4 context: developer and desktop IDE use a private coding lab; premium model APIs plan and review; default cloud-hosted agents are not connected to the private GPU
Context. The private lab uses a premium model for planning while Ollama remains private. Cloud-hosted agents are outside this home-lab design.

Cursor, Copilot, or Claude remains the planner. The private model is exposed through MCP, the Model Context Protocol: an open standard that lets the desktop IDE call a local program through named tools. Default vendor-hosted agents run away from the workstation [16] [17] [18]; enterprise private-connectivity and self-hosted configurations are possible, but they are separate designs. This home-lab bridge runs on the workstation, where it can reach private hardware without making Ollama public.

Local inference is not an air gap. The premium agent can access workspace files and receives the tool results through the vendor’s service. Halo does not hide that selected context from the planner; it keeps the delegated model generation on private hardware.

The workstation keeps the same stdio MCP server, the same six bounded coding tools, and the same environment settings. Stdio means the IDE launches the server and communicates through standard input and output rather than an MCP network port. The server reads the Ollama address from the environment, commonly through a gitignored .env file. Moving Ollama does not change what the IDE calls.

Deployment — one active host

Deployment variants: same-machine Ollama now; optional second private GPU over SSH; later Halo-class AMD with its inference backend still to validate
Variants. Only one host is active. Prefer SSH to that host’s localhost. A private-interface bind is optional. A public bind is not.

The inference host is simply the machine running Ollama. The roadmap changes that host in three controlled stages:

  1. Now: Ollama runs on the workstation, and the desktop-to-Ollama path is operational [13].
  2. Next: Ollama moves to a second private GPU host. SSH local forwarding — an encrypted connection that makes the remote service appear local — keeps Ollama bound to that host’s loopback address, which accepts connections only from the host itself. A robust example is ssh -N -T -o ExitOnForwardFailure=yes -L 127.0.0.1:11436:127.0.0.1:11434 user@<inference-host>; MCP then uses http://127.0.0.1:11436.
  3. Later: Halo takes the same host slot. Its AMD software backend still needs validation on the actual machine before any performance claim.

The security rule is unchanged: do not make Ollama internet-reachable. A 293-day SentinelLABS–Censys scan measured 175,108 internet-reachable Ollama hosts across 130 countries [5]; LeakIX separately documented 12,269 unauthenticated instances in its February 2026 dataset [6].

Current test status

Thirty-six mocked unit tests currently pass. Automated live integration checks also reach a real loopback-only Ollama through the stdio MCP server. A separate manual Cursor check invoked the MCP tools and executed the strong model’s returned test file successfully [13]. This validates the same-machine integration, not a complete IDE file-application workflow, the planned SSH deployment, broad model reliability, or Halo performance.

What a Halo box costs

The top-end chip considered here is AMD’s Ryzen AI Max+ 395: sixteen CPU cores, Radeon 8060S integrated graphics, and up to 128GB of soldered LPDDR5X unified memory. Framework says as much as 96GB can be graphics-addressable on its 128GB build [1]. That is memory capacity for quantized model weights larger than 16GB — not proof that a particular model, Ollama release, or AMD backend will run well.

Observed September 6, 2026 listings put 128GB systems between $3,449 and $4,349: Framework at $3,449, GMKtec at $3,649.99, and Beelink at $4,349 [1] [2] [3]. Published comparisons place earlier launch-era systems near $2,000 and attribute much of the later increase to soldered-memory pricing [3] [4]. Because that memory cannot be upgraded, capacity is a purchase-time decision. These figures are a dated snapshot, not a quotation.

What would justify buying it

Memory headroom matters only if larger models produce more complete and correct work on representative bounded tasks. Aider’s independent benchmark illustrates the risk: when models extract large methods from real Python projects, completion rates vary sharply and weaker models often skip code [7]. That benchmark covers hosted models, not this Halo proposal, so it supplies a useful test shape rather than a result.

Qwen’s vendor-authored report gives a second reason to compare sizes: within the Qwen2.5-Coder family, its 32-billion-parameter model scores above the 7-billion-parameter version on the published coding benchmarks [8]. Ollama lists the quantized 32B download at 20GB [11], already larger than a 16GB GPU before runtime overhead. Halo has room to evaluate it, but memory fit does not prove a quality gain.

Quality also has to fit the time budget. A direct community benchmark reports 4.7–4.9 output tokens per second for Llama 3.1 70B at 4-bit quantization on Strix Halo [9]. At five tokens per second, a 1,000-token answer takes about 200 seconds before prompt processing. That approaches the bridge’s current 300-second strong-model timeout [14], so a dense 70B model is practical only for bounded synchronous outputs unless the request contract changes. Backend and long-context results also vary materially [10] [12]. Replacing Ollama may require a client change unless the replacement preserves Ollama’s HTTP API.

The purchase criterion is therefore simple: benchmark named models, quantizations, context sizes, and backends on representative work; buy the memory headroom only if the quality gain is worth both the price and the wait. If the current models are already reliable enough, keep the money.

What is in the repo

The public repo provides the runnable MCP server, SSH-first deployment guidance, and dated operational and security evidence [13] [15]. Start with the working same-machine profile. Move to a private host only when that need is real, and consider Halo only after representative work shows that larger models would earn their additional cost. Keep machine-specific values out of git and review every local-model result before applying it.

References

  1. Framework — Framework Desktop with AMD Ryzen AI Max: Max+ 395 specs (16 cores, Radeon 8060S, LPDDR5X-8000), “up to 96GB of graphics addressable memory,” 128GB configuration at $3,449, sold as pre-order.
  2. Micro Center — GMKtec EVO-X2 listing: Ryzen AI Max+ 395, 128GB LPDDR5X-8000, 2TB SSD, $3,649.99.
  3. ComputingForGeeks — Ryzen AI Max+ 395 mini PCs compared (Aug 2026): side-by-side of Framework ($3,449), GMKtec ($3,649.99), Beelink GTR9 Pro ($4,349); documents the June-to-August price doubling and attributes it to DRAM contract pricing on soldered LPDDR5X.
  4. Liliputing — 128GB Ryzen AI Max+ 395 mini PCs roundup: earlier-2026 price baseline across nine vendors and the note that most of the 128GB can be used as VRAM.
  5. SentinelLABS + Censys — Silent Brothers (Jan 2026): joint 293-day internet scan measuring 175,108 unique exposed Ollama hosts across 130 countries (7.23M observations); 48% advertised tool-calling capability.
  6. LeakIX — 12,000 Ollama instances exposed (Feb 2026): 12,269 unauthenticated public instances, ~1,000 vulnerable to CVE-2024-37032, an unauthenticated remote-code-execution chain.
  7. Aider — Refactoring leaderboard and the benchmark design: 89 large-method extractions from real Python repositories, verified by parsing the output, built to provoke and quantify models eliding code on long outputs. Scores on the published board run from 92.1% at the top down to roughly 21% for the weakest listed configuration.
  8. Qwen team — Qwen2.5-Coder family report: six sizes trained identically to “verify the effectiveness of scaling”; 32B-Instruct outperforms 7B across the published code benchmarks (92.7 vs 88.4 on HumanEval) and scores 73.7 on Aider code repair, “performing comparably to GPT-4o.”
  9. ignasivt — Strix Halo Guide: community measurements for Llama 3.1 70B Q4_K_M report 4.7–4.9 output tokens per second across short prompt lengths on a Ryzen AI Max+ 395. This is a direct practitioner benchmark, not vendor certification.
  10. Strix Halo Wiki — llama.cpp performance: links reproducible backend comparisons and shows that prompt processing, token generation, driver choice, and long-context behavior can differ materially.
  11. Ollama — qwen2.5-coder library page: the 32b tag is a 20GB download in the default quantization.
  12. Digital Architects — Ryzen AI Max+ 395 local-LLM field notes: a practitioner report describing material stability and performance differences among Vulkan, ROCm, llama.cpp, and Ollama on Strix Halo. These observations motivate validation on the actual machine.
  13. slm-setup — Local acceptance results — 2026-09-06: reproducible commands, unit results, live same-machine MCP-to-Ollama checks, direct Cursor invocation, retries, and stated limitations.
  14. slm-setup — Ollama client implementation: current synchronous request behavior, 300-second strong-model timeout, and 4,096-token output cap.
  15. slm-setup — Repository security scan — 2026-09-06: refreshed Gitleaks history and committed-tree results at repository commit 277f6bd, GitHub secret-scanning alert state, deployment-safety checks, exact counts, and stated limitations.
  16. Cursor Docs — Cloud Agent security: each Cursor Cloud Agent runs in an isolated cloud virtual machine rather than on the developer’s laptop.
  17. GitHub Docs — About Copilot cloud agent: the hosted agent runs in an ephemeral GitHub Actions environment, while IDE agent mode edits in the local development environment.
  18. Anthropic Docs — Claude Code on the web: Anthropic-hosted sessions run in isolated Anthropic-managed virtual machines; organizations can also configure self-hosted cloud environments.

Web references and prices were checked on September 6, 2026. Retail prices and practitioner performance reports are time-sensitive.

Source: github.com/jmjava/slm-setup — spec.md, docs/c4.md, docs/roadmap.md
git clone https://github.com/jmjava/slm-setup.git

Tuesday, September 01, 2026

Local coding SLM — premium agents, private GPU, one MCP bridge

I still want the expensive model in the chair. I do not want it typing a hundred pytest functions. That work is often bounded and cheap to reject if it is wrong, making it a useful candidate for a small language model (SLM) running on my own hardware. The trick is getting Cursor, Copilot, or Claude to use that model without publishing its Ollama endpoint to the internet.

slm-setup is the setup I am using for that split. The premium agent stays the planner and the reviewer. A local process on the workstation talks to Ollama — an open-source server that runs language models on your own hardware. The local model never becomes “the model in the picker” — the IDE dropdown where you choose GPT or Claude as your chat model. It is a handful of tools the premium agent calls.

The thing that does not work

Cursor can override an OpenAI-compatible base URL, but those requests are assembled on Cursor’s servers. A workstation localhost or home-LAN Ollama URL is therefore outside the default request path; Cursor staff recommend a publicly reachable HTTPS endpoint for that configuration [1] [2] [3]. I do not want to expose Ollama publicly. The override is also shared by the OpenAI-model slot rather than configured per model, so it conflicts with keeping premium OpenAI-family models available for planning [4].

The same boundary applies to default vendor-hosted coding agents: Copilot’s cloud agent runs in GitHub Actions, while Anthropic-hosted Claude Code sessions run in Anthropic-managed virtual machines [5] [7] [8]. Enterprise self-hosted runners and organization-managed Claude environments are exceptions [6] [7], but they are separate designs. This home-lab bridge targets the machine in front of you: desktop Cursor, Copilot agent mode in the IDE, and local Claude Code.

A process on the workstation can reach a private GPU. The default vendor-hosted path does not share that network. That is the whole reason this is MCP — the Model Context Protocol, an open standard that lets a desktop IDE agent launch a local program and call it as a set of named tools — and not a model-provider hack.

Who does what

If the shape of the answer is obvious — tests, a rename, a bounded refactor, a summary, a first-pass review — I ask the local tools. If the problem is architectural, cross-system, or security-sensitive, I keep it on the premium model. If the local answer is thin or wrong, the premium model edits it. I expect to spend some premium tokens deciding and reviewing. I am trying not to spend them emitting the artifact.

you + premium agent
        │  plan, pick files, review
        ▼
local-coding-slm  (stdio, on the workstation)
        │  HTTP to localhost or an SSH local forward
        ▼
Ollama
   fast model              stronger model
 (everyday coding)      (harder local work)

The IDE and the MCP server live on the workstation. Ollama can run on that same machine or, after the planned two-machine test, on a second private host reached through SSH local forwarding — an encrypted connection that makes the remote Ollama service appear local. Machine-specific connection details never go in git.

What the local model is for

One server name: local-coding-slm. The MCP process does not run shell commands, write files, or open a network listener; it makes outbound HTTP calls to the configured Ollama API. It returns text — code, a diff, or markdown — and I decide whether to apply it. I send a few files, not the whole repository.

The tools have deliberately narrow responsibilities: write code, refactor, generate tests, explain, review, and check that Ollama is up. Each one has a short fixed system prompt. The test tool is told to write tests only. If the request is ambiguous, it should ask instead of inventing production changes.

The starter pair is a fast everyday model (qwen3.5:9b) and a stronger coding model (devstral-small-2). Use fast by default and escalate only when its answer is not good enough. The documented starting configuration uses 16K context — a working window of roughly 16,000 tokens; the stronger model may split work between CPU and GPU when GPU memory is tight [12]. Increase context only after measuring memory use on your own hardware.

What is tested now

Thirty-six mocked unit tests currently pass. Automated live integration checks also reach a real loopback-only Ollama — bound to 127.0.0.1 for access from this machine only — through the stdio MCP server. In a separate manual Cursor check, Cursor invoked the MCP tools and the returned strong-model test file passed both tests when executed [12]. This validates the current same-machine integration, not a complete IDE file-application workflow or broad model reliability.

What is in the repo

The public repo is the spec plus a running server, not a sketch. The server talks to the IDE over stdio — standard input and output, so it opens no network port of its own — and the same-machine path has been exercised against a real local Ollama runtime [12]. You also get a wrapper that starts the server, reads settings from the environment (commonly loaded from a gitignored .env), and templates for Cursor, VS Code Copilot, and Claude Code. Machine-specific values are never committed.

Treat local output as untrusted. Apply it, trim it, or throw it away. The premium agent can access workspace files and sends selected context through the vendor’s service; the SLM sees only the snippets passed in the tool call. There is no automatic classifier deciding which model to call. The project instructions keep the rule explicit: bounded mechanical work can go to the local tools; ambiguous, architectural, or security-sensitive work stays with the premium model.

Do not expose Ollama publicly. No ngrok, Cloudflare Tunnel, or router port-forward that makes the API internet-reachable. Ollama binds to localhost by default, and its local API requires no authentication [9]. A 293-day SentinelLABS–Censys joint scan measured 175,108 unique internet-reachable Ollama hosts across 130 countries [10], and LeakIX found roughly a thousand of the instances it counted still vulnerable to a known unauthenticated remote-code-execution chain [11]. For a second host, keep remote Ollama on 127.0.0.1:11434 and create a workstation-only forward: ssh -N -T -o ExitOnForwardFailure=yes -L 127.0.0.1:11436:127.0.0.1:11434 user@<inference-host>. Then point MCP at http://127.0.0.1:11436. A private-interface bind is only a firewall-restricted fallback. The current dated repository scan found no detected leaks or GitHub secret-scanning alerts, while noting that a clean scan is not proof of absence [13].

If you already pay for a premium coding agent and have a private GPU, this is the shape to start from. Clone the repo, set OLLAMA_BASE_URL in the gitignored .env file, and measure whether the small model is good enough for the bounded work you actually do.

The host side of this has a roadmap now: an AMD Halo-class box as a later private Ollama host, with the C4 views that show what changes and what does not. That is the follow-up post, Same MCP, next host — Halo on the slm-setup roadmap.

References

  1. Cursor Docs — Custom API keys: “Your API key … is sent to our backend with every request because all requests are routed through Cursor’s servers for final prompt building.” Also notes custom keys apply to chat models only; Tab completion stays on Cursor’s models.
  2. Cursor Forum (staff reply, Feb 2026) — Connecting local AI server to Cursor does not work: “All BYOK requests go through Cursor’s servers to build prompts, so localhost or local network addresses won’t work because the server can’t reach them. You’ll need to expose your Ollama instance as a public HTTPS endpoint using something like ngrok or Cloudflare Tunnel.”
  3. Cursor Forum (staff reply, Mar 2026) — How to use Cursor directly with only my model API?: “There is currently no option to have Cursor communicate directly with your own server without going through Cursor’s backend.” See also staff confirmation that a full bypass is an architectural limitation: “Prompt building, context retrieval, and Cursor Tab and Agent run on our side.”
  4. Cursor Forum (staff reply) — routing explanation: with a custom key plus override, “requests for OpenAI-family models (anything that’s not claude-* and not gemini-*) go to your custom endpoint”; the base URL is a single global setting, not per-model.
  5. GitHub Docs — About Copilot cloud agent: the coding agent “has access to its own ephemeral development environment, powered by GitHub Actions,” and is “distinct from the ‘agent mode’ feature available in your IDE,” which “makes autonomous edits directly in your local development environment.”
  6. GitHub Docs — Customize the agent environment: self-hosted runners can give Copilot access to internal network resources. This is an enterprise exception to GitHub’s default hosted environment. See also the agent firewall documentation: the cloud agent’s internet access is restricted inside the GitHub Actions environment.
  7. Anthropic — Claude Code on the web: Anthropic-hosted sessions run in isolated Anthropic-managed VMs; organizations can also configure self-hosted cloud environments.
  8. Anthropic — Configure cloud environments: all outbound traffic from cloud sessions passes through Anthropic’s network proxy with allowlist levels (None / Trusted / Custom / Full).
  9. Ollama — FAQ and API authentication: Ollama binds to 127.0.0.1:11434 by default, and no authentication is required for its local API.
  10. SentinelLABS + Censys — Silent Brothers (Jan 2026): joint 293-day internet scan; 175,108 unique exposed Ollama hosts across 130 countries, 7.23M observations, 48% advertising tool-calling. Censys’s earlier single-day snapshot (Ollama Drama) found 10.6K instances, 1.5K directly promptable.
  11. LeakIX — 12,000 Ollama instances exposed (Feb 2026): 12,269 unauthenticated instances, roughly 1,000 running versions vulnerable to CVE-2024-37032 (“Probllama”), an unauthenticated path-traversal-to-RCE chain.
  12. slm-setup — Local acceptance results — 2026-09-06: reproducible commands, hardware details, unit results, live same-machine MCP-to-Ollama checks, and a direct Cursor invocation with executed generated tests.
  13. slm-setup — Repository security scan — 2026-09-06: the refreshed Gitleaks scan covered repository commit 277f6bd and requested all refs; GitHub returned no secret-scanning alerts; committed-tree and loopback deployment checks passed. The report gives exact scan counts and limits.

Web references were checked on September 6, 2026.

Source: github.com/jmjava/slm-setup — start with spec.md
git clone https://github.com/jmjava/slm-setup.git

Sunday, August 30, 2026

Cursor sessions that survive the chat — tracking work with Obsidian MCP

A Cursor chat is a terrible filing cabinet. It is excellent while it is open. It is gone when you start the next one — or when a Cloud Agent finishes a wave on a different machine. I wanted session memory I can open next week: what we did, which commit we left on, what we decided, and what is still open. That is what obsidian-mcp writes.

Holographic coder connected to floating session notes
The bet: session notes should be files, not a vendor memory API.

The server is local MCP over stdio. Cursor (or Copilot) calls tools. The tools read and write ordinary Markdown in an Obsidian vault. Obsidian does not need to be running. There is no community plugin and no hosted memory database. If I can open the file in a text editor, the memory is real.

What I actually keep

Each project gets one folder under AI Memory/Projects/<slug>/:

Project State.md          # current objective, in-progress, next steps
Sessions/YYYY-MM-DD.md    # timestamped sections for that day
Decisions/YYYY-MM-DD-*.md # one file per durable choice

Project State is the hot brief — what this repo is for right now. It is replaced when status changes. It is not a diary.

Sessions are the diary. capture_work_session appends a timestamped section to today. If I pass the repo path, the note records branch, short SHA, dirty flag, and a short file list. Full diffs never go in. I do not want a second copy of git.

Decisions are the “why.” Architecture choices that the next agent should not re-litigate. Same slug on the same day gets -2, never an overwrite.

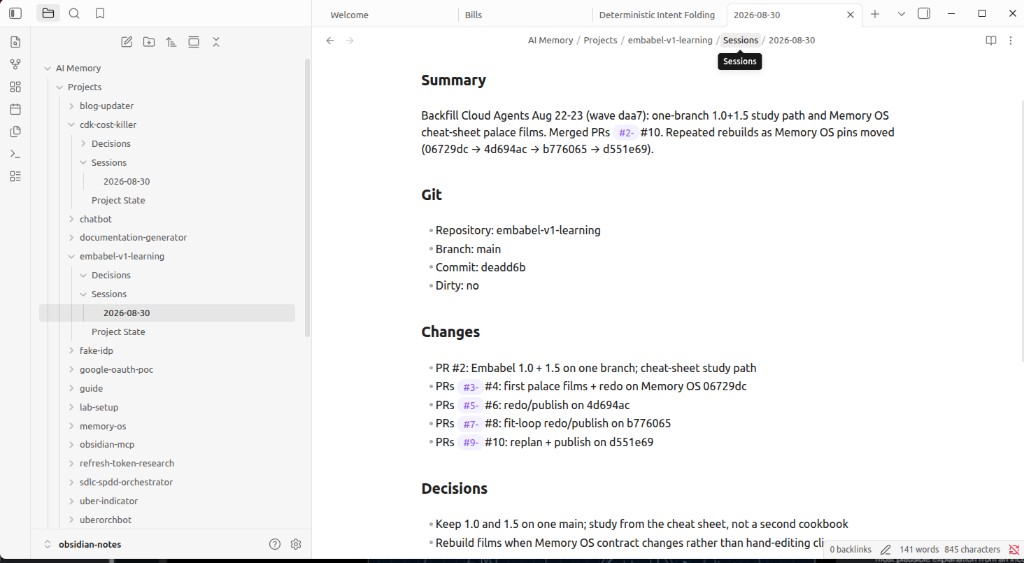
This morning’s vault looks like this — a real session note for embabel-v1-learning, not a mock:

Obsidian vault showing AI Memory projects and the 2026-08-30 embabel-v1-learning session
Obsidian on the same files the MCP server wrote: summary, git SHA deadd6b, PRs #2–#10, the 1.0+1.5 branch decision.

The sidebar is the map: blog-updater, cdk-cost-killer, embabel-v1-learning, obsidian-mcp, and the rest of the lab. I do not keep one giant note. I keep one project folder and let the dated session files accumulate. When I open Cursor on that repo tomorrow, the first useful call is not “read the whole vault.” It is get_project_context for that slug — Project State plus the newest sessions and decisions.

The loop I run in Cursor

Cursor connected to an Obsidian vault through MCP stdio
Cursor (or Copilot) talks MCP stdio. The vault is the source of truth.

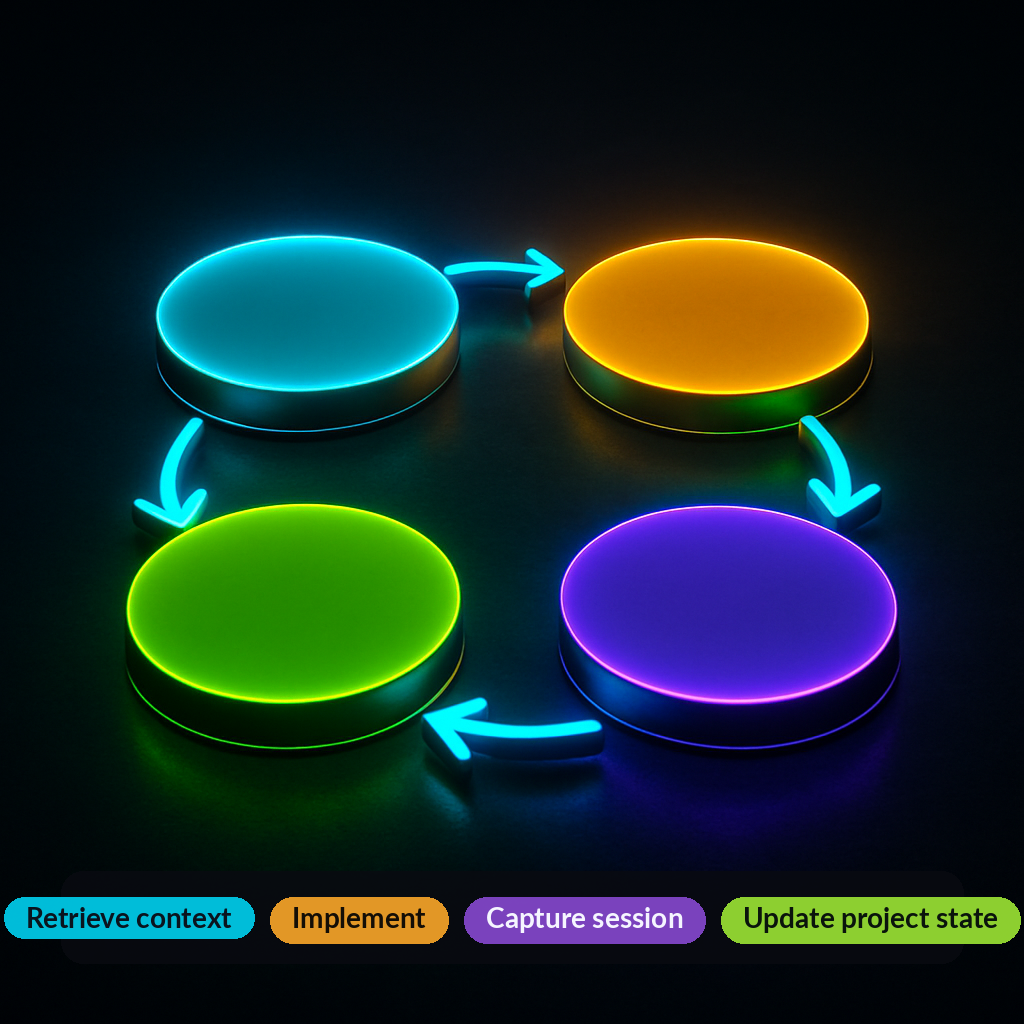
  1. Before substantial work — get_project_context. Continuing a feature, debugging a known area, or answering “why is it like this?” Empty sections if the project is new. Never the entire vault.
  2. After meaningful work — capture_work_session with a short summary, changes, decisions, and next steps. Pass repository_path so the git snapshot lands in the same note.
  3. When a choice should stick — record_decision. Example from that screenshot: keep Embabel 1.0 and 1.5 on one main; study from the cheat sheet, not a second cookbook.
  4. When overall status moves — update_project_state. Concise. Current tense.

Lookup is local: search_memory over that project’s files, read_note for one vault-relative path, append_daily_note for a line that belongs on today’s Daily/YYYY-MM-DD.md instead of a project folder.

Retrieve context, implement, capture session, update project state
Retrieve → implement → capture → update state. Skip the capture when the change was a typo.

What is not persisted

The Cursor rule that ships with the installer is the product as much as the tools. Typo fixes, formatting-only edits, and one-line mechanical changes are not memory. If every keystroke becomes a session section, I will stop reading the vault — and so will the next agent.

Secrets never land in the vault on purpose. Values that look like keys, tokens, JWTs, or password= assignments are replaced with [redacted-secret] before write. I also never persist .env contents, database credentials, or customer data. Summarize the incident; do not paste the token.

Paths are confined to OBSIDIAN_VAULT_PATH. Absolute note paths, ../ traversal, and symlink escapes are rejected. This is not a general filesystem API. Writes are atomic.

Wire it once

export OBSIDIAN_VAULT_PATH="$HOME/Documents/ObsidianVault"
uv sync

./scripts/install-project.sh \
  --project /path/to/your-app \
  --vault "$OBSIDIAN_VAULT_PATH"

The installer merges .cursor/mcp.json (it does not wipe unrelated servers) and drops the Cursor rule plus Copilot instructions so both assistants use the same habits. Point the env var at a real vault directory. The server does not auto-load .env files.

I already have a product-shaped write-up of the seven tools. This post is the part I needed after the first week of using it: the vault is how I keep Cursor sessions and ongoing work in one place I can see. Open Obsidian when you want the graph. Leave it closed when you just need the assistant to remember the last SHA.

Source: github.com/jmjava/obsidian-mcp

Friday, August 28, 2026

The DIF test engine — prove the three layers without collapsing them

A plan that cannot fail in an interesting way is just more markdown. The last post said DIF, the orchestrator, and Embabel answer different questions. This post is the test engine that keeps them from collapsing into one runtime.

Follow-up to Three layers, one day. Source: the working test flow in jmjava/embabel-dif and the integration ladder in docs/ORCH_INTEGRATION_ROADMAP.md.

What “test engine” means here

Not a new product. Not a second daily driver. A stacked set of checks where each rung is allowed to fail before we spend complexity on the next:

./mvnw test                 # unit + CLI + FoldContractTest
                            # EmbabelLivePlatformTest skipped unless DIF_LIVE_EMBABEL=1
./scripts/dif-orch-smoke.sh # FEAT-001 ready + T03; FEAT-099 exit 1
./scripts/dif-orch-day.sh   # fold twice / architect / review / plan --projection
                            # skip when CLI or snapshots missing
./scripts/dif-live-e2e.sh   # orch Guide+Neo4j + JSONL quote + live GOAP

Default CI is the first two boxes. Live Guide and Embabel are opt-in. They reuse the orchestrator’s existing tests/test-guide-stack-live.sh. They do not put Embabel or Guide inside sdlc.sh next.

The engine’s job. Prove the three systems can talk. Prove a missing DIF checkout is skip, not a broken day. Prove a contradictory canvas cannot earn Ready For Coding. Never start a JVM to run next.

Rung A — five named checks, not prose

FoldContractTest is step 1 of the fold iteration plan. The five success criteria are tests:

Check What fails if we are wrong
Same accepted canvas → same model Nothing downstream is trustworthy
Review fails without “looks correct” login-auth-broken still prints RESULT: PASS
Syntax variance does not flip invariants A DTO rename (FEAT-070) changes what must stay true
Open T## is a MissingObligation T03 on FEAT-001 disappears into a checklist
Requirement vs non-goal blocks Ready For Coding FEAT-099 pagination clash still looks green

Harvested canvases under examples/canvases/ are the corpus. The fold learns from real REASONS files, not imagined IR. Adding a backend must not change the CLI or the canvas schema.

Rungs C–D — a script can trust the gate

dif-fold.sh writes a projection and a stable .gate.json. Smoke does not parse stdout for meaning. It reads JSON and exit codes:

{
  "workId": "FEAT-001-order-status-api",
  "readyForImplementation": true,
  "blockingConflicts": [],
  "missingObligations": ["T03"]
}

dif-orch-smoke.sh folds FEAT-001 (exit 0, ready, T03 missing) and FEAT-099 (exit 1, blocking pagination clash). If a sibling orch checkout is present, it folds the live examples/spring-boot-order-api canvas too. Then it hits the silent attach:

DIF_DISABLED=1 check-canvas.sh …   →  dif=skipped   (exit 0)
check-canvas.sh FEAT-001           →  dif=ready     (exit 0)
check-canvas.sh FEAT-099           →  dif=blocked   (exit 1)

One line. Agents do not get a fold dump. Missing DIF is skip, not a new ritual. That is the same opt-in shape as Guide.

Rung G — a scripted day, no Embabel

dif-orch-day.sh is the cheap “full day.” It does not start Embabel, Guide MCP, or replace sdlc.sh next.

  1. Fold the same FEAT-001 canvas twice. The two .gate.json files must cmp equal.
  2. Architect FEAT-001 → dif=ready, T03 still a missing obligation.
  3. Architect FEAT-099 → exit 1, dif=blocked.
  4. Review the orch order-status snapshots: dropping auth fails. A DTO rename still passes.
  5. plan --projection builds a VerificationPlan from the folded model. No markdown re-parse.
  6. Guide JSONL is an optional quote (Decision / Pitfall), not a gate.
  7. Missing CLI or missing snapshots → dif=skipped. Present snapshots that drop a safeguard → dif=blocked.

Review uses examples/snapshots/order-status-*.json and the canvas safeguard paths — not the old login fixtures. Syntax-ok vs auth-broken is the whole point: a rename is legal; a dropped safeguard is not.

Rungs H–J — live, still not inside next

dif-live-e2e.sh is the three-way path that already passed here. First it asserts sdlc-engine is not a JVM — help must not mention Spring or Embabel. Then it reuses the orch Guide+Neo4j harness, runs the scripted day, quotes DIF JSONL through GuideClient under a unique Work ID (FEAT-DIF-LIVE-… so it does not collide with orch’s already-projected FEAT-001), and boots the Embabel Spring platform.

Live Embabel (EmbabelLivePlatformTest, DIF_LIVE_EMBABEL=1) runs the fixture GOAP path:

UserInput
  → captureRequest → interpretIntent → foldIntent
  → analyzeRepository → planVerification
  → VerificationPlan (readyForImplementation, missing rotation IT)

The refresh-token wording uses FixtureIntentInterpreter — no LLM. A second test plans an already-folded orch canvas without re-parsing markdown. Conflicts stay on the VerificationPlan (readyForImplementation=false). They are not a GOAP precondition Embabel 1.5 cannot treat as an action post.

Orch CI does not need Maven. It uses tests/fixtures/dif-fold-stub.sh so detect-and-skip / fail-closed can be proven with a fake CLI: skipped, ready, or blocked.

What would fail the engine

The ladder is the falsification list from the last post, turned into commands:

  • Two folds of the same canvas disagree → day step 1 fails.
  • A requirement vs non-goal pair still looks ready → smoke / architect on FEAT-099 fails.
  • An open T03 does not show up → gate assertion fails.
  • A DTO rename flips an invariant → SyntaxVarianceTest / review syntax-ok fails.
  • Review cannot fail a dropped safeguard without “looks correct” → auth-broken still passes.
  • sdlc-engine --help mentions Embabel → live E2E step 0 fails.
  • Missing DIF breaks the orch day → skip tests fail.

If people stop reading the canvas because they treat the JSON as source of truth, we failed even if every script is green. The projection stays regenerable and disposable.

Source: github.com/jmjava/embabel-dif
Previous: Three layers, one day — DIF, the orchestrator, and Embabel
Related: sdlc-spdd-orchestrator · Embabel

Thursday, August 27, 2026

Three layers, one day — DIF, the orchestrator, and Embabel

Reliable AI engineering does not require every component to be deterministic. It requires determinism at the boundaries where repeatability, traceability, and correctness matter. That is the sentence embabel-dif is testing — not a Merly reimplementation, and not a second daily driver.

Use stochastic reasoning to discover knowledge. Use deterministic representations to operationalize it once it is understood.

The hole the runbook cannot close

Coding agents are good at reading a repository and sounding like they understand it. The understanding is usually implicit and disposable:

prompt + files + luck  →  a one-off theory of the system  →  a patch

The next session starts from zero. It may decide that sessionToken was incidental, that Google login can move, or that an existing test is optional. Nothing in the process remembers which of those beliefs were load-bearing.

sdlc-spdd-orchestrator already attacks the process half: one Work ID, one REASONS Canvas, one phase at a time. Assistants are not allowed to invent a parallel workflow. That is necessary and not sufficient. The canvas is still prose. Architect, review, and sync still ask an LLM to compare the canvas to a diff. Comparison is where implicit intent creeps back in.

Process gates ask “do the prerequisite files exist?” They do not ask “did this canvas contradict itself?” or “did this diff drop a safeguard?”

The remaining hole is checkability. You can follow the runbook perfectly and still ship a contradictory canvas, mark Ready For Coding in prose, or pass review because the change “looks right.”

Three questions, three systems

Planning / requirements     why are we doing this?
REASONS Canvas              what must ship (human contract)
DIF SemanticModel           what must remain true (machine contract)
Embabel GOAP                what action to take on typed facts (optional)
DICE / Guide graph          what did we learn before (retrieval)
SDLC phases                 who is allowed to act
Layer Owns this question Must not own
Orchestrator Who acts when? One Work ID, one canvas, one phase. Folding facts. Starting a JVM. Being a planner.
DIF What must stay true? Same accepted canvas → same model. Conflicts fail closed. Daily orientation. Picking the Work ID. Replacing the canvas.
Embabel What action to take on already folded facts (optional JVM path). The fold itself. sdlc.sh next. The human contract.

Git stores what changed. A DIF-style layer stores why it had to, and what must still be true. Embabel, when present, decides what to do next. The orchestrator decides who is allowed to act.

They stay three repos on purpose. Merging Embabel or DIF into the orchestrator would fight its design: it is an installable operating model, not a compiled agent runtime. The contract between them is a file:

spdd/canvas/<WORK-ID>.md            human source of truth
        │
        ▼  fold (deterministic after accept)
.dif/projections/<WORK-ID>.json     machine projection (disposable)
.dif/projections/<WORK-ID>.gate.json
        │
        └─ orch may read the exit code
           it does not start the JVM to run next

A canvas is already a candidate intent. We do not need a new human artifact. We need a projection.

DICE is not DIF

The orchestrator already has Guide DICE as an optional working store. The acronyms smash together. The jobs do not.

DICE  = retrieve what we already believe
        (lessons, decisions, pitfalls, area subgraphs)

DIF   = freeze what must remain true, then verify it
        (intents, invariants, conflicts, obligations)

DICE answers “what did previous work in this area learn?” DIF answers “may this change proceed, and did it preserve the contract?” Both can project from the same committed files. Neither replaces the canvas or the lessons ledger. The ledger stays the system of record; SQLite, Guide, and .dif/projections/ are regenerable.

What landed today

Yesterday’s prototype proved a typed fold on a refresh-token fixture. Today the fold attaches to real REASONS canvases and fails closed in a way a script can trust.

./mvnw test
./scripts/dif-orch-smoke.sh
./scripts/dif-fold.sh --canvas examples/canvases/FEAT-001-order-status-api.md
./scripts/dif-fold.sh architect --projection .dif/projections/FEAT-099-pagination-conflict.json
./scripts/dif-fold.sh review --before examples/snapshots/login-before.json \
                            --after examples/snapshots/login-auth-broken.json

dif-fold does not start Embabel. fold writes a projection and a stable .gate.json (readyForImplementation, blockingConflicts, missingObligations) that a script can read without parsing stdout. architect and review fail closed: exit 1 means not Ready For Coding, or invariants were not preserved.

After a fold, “ready” is allowed to mean this:

  • A mutually exclusive pair (“must paginate” vs “non-goal: pagination”) blocks Ready For Coding. The next command is clarification, not code. That is FEAT-099.
  • An open operation (T03) shows up as a MissingObligation, not a forgotten checklist box.
  • Two folds of the same accepted canvas produce the same model.
  • Syntax may change (DTO names, test style). Preservation of auth and unrelated endpoints must not. That is FEAT-070.
  • Review can fail a required safeguard without asking an LLM whether the change looks correct.

The ten fold-iteration steps from the steal list are implemented: fold contract tests, harvested canvases, heading classification, quoted conflicts, open-T## obligations, syntax-out-of-invariants, an optional Alloy sketch, architect/review attach, and a plan path that builds a VerificationPlan without making Guide required.

Take the idea only as far as it makes sense

The knowledge that actually hurts is not “which slash command is next.” The orchestrator already answers that. The tax is shipping a contradictory canvas or a dropped safeguard while the runbook stays green.

The filter for every attach:

Does this make the existing orchestrator commands harder to get wrong, without adding a new ritual?
Do Do not
Keep claim → next → architect → one T## → review as the only user surface Add dif-fold.sh next as a second daily driver
When DIF is installed, architect cannot earn Ready For Coding on a requirement vs non-goal clash Teach users fold / projection / .gate.json as a parallel workflow
When DIF is missing, the day is unchanged Require Embabel, Java, or OpenAI to run next
Review can fail a dropped safeguard without “looks correct” Replace sdlc.sh gate process checks with the fold

A new orchestrator user who never heard of DIF should have a better day if it is installed, and the same day if it is not. Silent fail-closed on existing architect / code is DIF doing DIF’s job: the readiness string becomes earned. The runbook stays the orchestrator’s. Embabel stays later and optional. Wiring it into next would be the other collapse.

Path, and what would falsify it

1. DIF      canvas → SemanticModel CLI      no Embabel          (working)
2. Orch     architect / code attach         if CLI present      (silent, opt-in)
3. DIF      Embabel GOAP for JVM targets    orch still picks Work ID / T##
4. Optional project invariants into Guide   shared vocabulary, still not required

Step 1 first: if the same canvas does not fold the same way twice, nothing downstream is trustworthy. Step 2 next: attaching an exit code is cheaper than inventing a new phase. Embabel later. Guide last — retrieval already works.

The idea is wrong if two folds disagree, if review still cannot fail a safeguard without “looks correct,” if a DTO rename flips a required invariant, if sdlc.sh next starts a JVM, or if developers need a second next to have a correct day. The projection must stay regenerable. If people stop reading the canvas, we failed even if the JSON is pretty.

Source: github.com/jmjava/embabel-dif
Publication plan: BLOG_DIF_ORCH_EMBABEL.md
Related: sdlc-spdd-orchestrator · Embabel · embabel-v1-learning